Public Response: Verifier Check from Epoch AI
Epoch AI reviewed 50 of the 122 public ALE v1.1 tasks and reported that 22 of them can be scored at 100% without the intended work. The review sorts these into three groups: public answers, lax graders and grader tampering. Our response to each group is below, followed by the detail for every task and the run data behind it.
These issues exist hypothetically, but they rarely occur in practice. Each one was found by attacking the verifier as a white box, and agents never see the verifier while they run. On the 13 lax-grader and tampering tasks, 0 of 1,059 trajectories exploited the verifier. Across all 22 flagged tasks, 3 of 1,617 trajectories (0.19%) reached a full score through a flagged route. This count excludes the two tasks whose network rule was never shown to the agent, which PR #136 now enforces.
1. Public answer (9 tasks)
Flagged issue: answers are public online, and agents can look them up.
Justification: closed-book tasks state the rule (no internet access) in the prompt, and agents follow it where it is stated. PR #136 adds enforced network isolation in an upcoming release, and we will extend this egress control to more tasks.
Evidence: 0 of 236 runs looked up an answer when the prompt forbade it. Details
2. Lax grader (8 tasks)
Flagged issue: the grader accepts trivial or made-up outputs.
Justification: a deterministic check approximates expert judgment, so anyone reading it can find a way to pass. This holds for any grader that stands in for an LLM judge, especially on video, animation, medical imaging or linguistic meaning, and it is how the review built its examples. Agents never see the verifier, so they cannot aim at these gaps and do the task instead.
Evidence: 0 of 242 trajectories took the shortcuts the review describes. Details
3. Grader tampering (5 tasks)
Flagged issue: the agent can modify the grader before it runs.
Justification: the verifier and hidden references reach the VM only after the agent finishes, so there is nothing to tamper with.
Evidence: 0 of 412 trajectories read grader code or hidden references. Details
The flagged tasks still distinguish strong models from weak ones
A grader that paid for trivial work would give every model a high score. On 15 of the 22 flagged tasks, the best and worst model families differ by at least 0.5 in mean score, and no flagged task gives every family a high score. Details
Based on all 2,769 recorded runs on the 22 flagged tasks, 1,783 with full trajectories.
1. Public answer (9 tasks)
Flagged: answers are public online, and agents can look them up.
Justification: The closed-book rule is followed where it is stated.
Today ALE controls outside access in the prompt. Tasks that must be solved closed-book say so in the instructions. On the three flagged tasks that carry this rule, none of the 236 runs looked up an answer.
Two flagged tasks, wsi_tumor_localization_1 and ketcher_smiles_reproduction, turn the network off only in the task card. The agent never sees the task card, so it was never told. On these two tasks, 51 of 166 trajectories looked up the answer. Both tasks will run under enforced network control once PR #136 ships. The other six flagged tasks have no restriction, and 14 of 479 trajectories (2.9%) looked something up.
| Task | Rule the agent saw | Trajectories | Looked up an answer | Of those, full score |
|---|---|---|---|---|
| Prompt forbids outside sources | ||||
| legal_dr_fees_01 | Closed-book rule in the prompt | 79 | 0 | 0 |
| atlas_outpost_graybox_navigation | "Do not rely on internet access" | 70 | 0 | 0 |
| lenacapavir_sar_table2_extraction | "Do not rely on web search or external answer sources" | 87 | 0 | 0 |
| Restriction only in the task card, not shown to the agent | ||||
| wsi_tumor_localization_1 | None | 86 | 21 | 18 |
| ketcher_smiles_reproduction | None | 80 | 30 | 25 |
| No restriction | ||||
| tris_crackme | None | 78 | 0 | 0 |
| legal_ma_consistency_audit_01 | None | 75 | 2 | 1 |
| merfish_image_decoding_segmentation_1 | None | 84 | 2 | 0 |
| abm_hangzhou_metro | None | 79 | 1 | 1 |
| power_10kv_feeder_reliability_001 | None | 81 | 9 | 1 |
| amber_three_stage_mmgbsa_workflow_instance_1 | None | 82 | 0 | 0 |
Network isolation will be enforced
rdi-berkeley/agents-last-exam#136 enforces the network setting in the task card. A task with its network turned off runs on a VM with no public address. Outbound traffic goes through a proxy that allows only listed hosts, and a check inside the VM confirms that direct connections are blocked before the agent starts. If an environment cannot provide this, the task stops before a VM is created. This will be enforced in an upcoming release.
"Looked up an answer" counts a tool call that fetched or searched for the answer source the review names. These are the CAMELYON16 tumor_001.xml annotation, the 7YY / ensitrelvir SMILES on RCSB or PubChem, the starfish benchmark results file, the original public filings, code-host searches for the metro simulator, and the ALE repository and dataset. Package installs, model weights and documentation pages are not counted.
| Task | Flagged issue | Justification |
|---|---|---|
| tris_crackme | The key generator is in the public grader code. | 0 of 78 trajectories looked for it. 2 full scores in 120 runs. |
| legal_ma_consistency_audit_01 | The task description and grader reveal the inconsistencies. | 2 of 75 trajectories fetched outside filings. 1 full score in 127 runs. |
| merfish_image_decoding_segmentation_1 | The answer key is a public starfish file. | 2 of 84 trajectories downloaded it, and neither scored above 0.6. No run in 136 reached full score. |
| abm_hangzhou_metro | The grader's simulator is public. | 1 of 79 trajectories searched code hosts for it. 20 of the 21 full-score trajectories made no lookup. |
| wsi_tumor_localization_1 | The CAMELYON16 annotation is public, and network-off is not enforced. | The rule was only in the task card, so the agent was never told. 21 of 86 trajectories looked it up. PR #136 enforces the rule. |
| power_10kv_feeder_reliability_001 | A public script rebuilds the answer key. | 9 of 81 trajectories went looking, and 1 of them reached full score. 1 full score in 135 runs overall. |
| ketcher_smiles_reproduction | The SMILES is on RCSB, and network-off is not enforced. | Same as wsi. The rule was only in the task card, and 30 of 80 trajectories looked it up. PR #136 enforces the rule. |
| amber_three_stage_mmgbsa_workflow_instance_1 | Public tests include a passing file set. | 0 of 82 trajectories used them. 1 full score in 135 runs. |
| legal_dr_fees_01 | The 15 amounts are in the public grader. | The prompt is closed-book, and none of the 79 trajectories made a web call. |
2. Lax grader (8 tasks)
Flagged: the grader accepts trivial or made-up outputs.
Justification: Agents do not see the verifier, so they do not target it.
A verifier is easy to game only if you can see it
Each ALE grader turns what a domain expert would accept into checks a program can run: waveforms, distributions, tolerance bands and file contracts. If you read such a program looking for a way around it, you will find one. That holds for any verifier that stands in for an LLM judge, especially on video, animation, medical imaging or linguistic meaning. We use deterministic checks on purpose, because a model judge brings its own bias and variance.
The agent never sees the verifier, so 0 of 242 trajectories took the shortcut
The grader and the hidden references are copied to the VM after the agent session ends. During the run the agent has the prompt, the inputs and its tools. It does not know the thresholds, kernels, count bands or field lists the review's examples rely on.
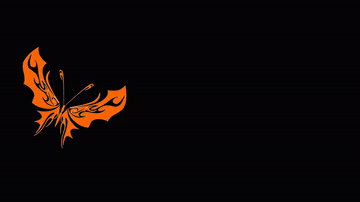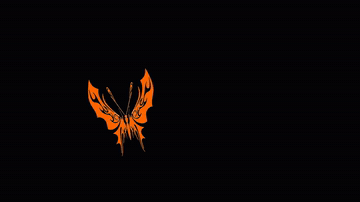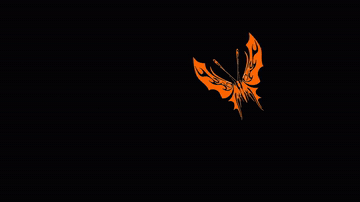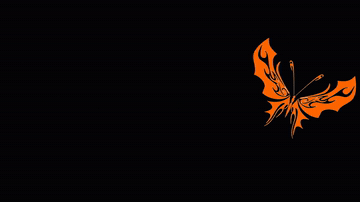
The butterfly task is a good example. The agent gets a single static butterfly illustration and has to turn it into an animation: cut the body and wings apart, flap the wings through exactly four cycles, and fly the butterfly along a smooth curved path, exported as a short MP4. To grade it, we measure how the silhouette width changes over four flap cycles, and we measure the flight path, because LLM judges for video cannot yet score motion reliably. Someone could pass this check by flapping a different shape. An agent asked to animate a butterfly has no reason to do that. All 77 butterfly trajectories split the body from the wings, and none used the whole-image squeeze the review describes.
These are the final output.mp4 files from six archived runs, with the score each one received. The pass line is 0.65. Every passing render is a real wing-flap animation on a curved path. The Gemini 3.1 Pro render never removed the white background and was capped at 0.55.
A made-up answer still has to be produced
The review says fabricated outputs can score full marks. Each of its examples was built by reading the grader first. Without the grader, an output that passes these checks has to come from doing the work. On particle_filter_nonlinear_tracking there are 0 full scores in 132 runs, and on atlas_outpost_graybox_navigation there are 0 in 71.
Some final stages are checked within a budget
For some tasks the last stage is very expensive: a full replication run, an independent dose calculation, a long transient simulation. For these tasks the agent hands in a runnable script and its outputs, and the grader checks what fits within the evaluation budget. The agents still do the work. On atwood, 78 of 85 trajectories ran the regression code, and none copied the paper's numbers into the code column.
| Task | Flagged issue | Justification |
|---|---|---|
| butterfly_flap_animation | Squeezing the uncut image along a wavy path scores 100%. | The flap-width and path metrics stand in for a video judge, which is not reliable yet. All 77 trajectories split the wings, and none squeezed the whole image. Weak renders are capped at 0.55, below the 0.65 pass line. |
| atwood_2022_measles_vaccine_reproduction | Code coefficients are checked against the paper, and logs are only format-checked. | Re-running the package is the stage checked within budget, so the agent hands in the run. 78 of 85 trajectories ran the code, and none copied the paper's values. |
| particle_filter_nonlinear_tracking | Submitting the agent's own simulated truth scores 100%. | 0 full scores in 132 runs. The grader recomputes the Tier 1 Kalman filter from the submitted observations and recomputes every RMSE from the arrays. |
| internal_employee_agent_instance_1 | Checks read topic words and self-declared tool names. | The 102 checks stand in for an HR/IT reviewer. They are hidden from the agent, so passing 92 of them means answering the conversations. |
| yeast_colony_detection | Stacked points plus one outlier pass the MMD test. | Building those points needs the hidden count band and kernel settings. 14 full scores in 137 runs. |
| Analog_Active | No connectivity check, and made-up results score. | Scoring reads the circuit.raw file that LTspice writes. Faking a waveform that meets the ripple and load targets is harder than building the circuit. |
| prostate_imrt_matrad_reproduction | A made-up dose earns 73 of 98 points. | The hard gate needs a DICOM plan and dose that match the CT's frame of reference and geometry, and coverage is recomputed from the submitted dose grid. 8 full scores in 150 runs. |
| atlas_outpost_graybox_navigation | Named empty glTF objects plus markers score. | The grader measures routes, zone budgets, cover and line of sight from where the nodes are placed, which is what a blockout delivers. 0 full scores in 71 runs. |
3. Grader tampering (5 tasks)
Flagged: the agent can modify the grader before it runs.
Justification: The grader is not on the VM while the agent works.
All five findings assume the agent can plant something the grader will later run or read: a module in the evaluation folder, a script that prints a score, or a reduction script that copies staged answers. Each needs the agent to know where the grader will be written, what it imports or what output it reads. None of this is on the VM during the run, because the verifier and the hidden references are uploaded after the session ends.
Across 412 trajectories on these five tasks, no agent read grader code or a hidden reference. On dit_pipeline_cfg_alignment_fid_256_001, where the review says a three-line file scores 100%, there is 1 full score in 133 runs. On hst_acs_wfc_visit_reduction there are none in 94.
| Task | Flagged issue | Justification |
|---|---|---|
| mp_checkpoint_consolidation_v2 | The grader runs a program from the input folder. | The prompt marks input/ as read-only, and the grader also compares tensors and logits directly against the hidden reference. |
| cailian_road_highway_alignment_2 | The grader runs from a folder the agent can write to. | The verifier is written there after the agent finishes. 3 full scores in 120 runs. |
| dit_pipeline_cfg_alignment_fid_256_001 | A three-line file that prints a perfect score passes. | The agent never sees how the scorer reads its output. 1 full score in 133 runs. |
| lenacapavir_sar_table2_extraction | A Python file planted in Temp can take over the grader. | Planting a module needs the verifier's path and imports, and neither exists during the run. |
| hst_acs_wfc_visit_reduction | The script runs after hidden answers are staged. | The references arrive after the session ends. 0 full scores in 94 runs. |
The flagged tasks clearly distinguish strong models from weak ones
On 15 of the 22 flagged tasks, the best and worst model families differ by at least 0.5 in mean score, and on 8 of them by the full 1.0. No flagged task gives every family a high score.
If a grader paid for trivial work, every model would score well and the row would be uniformly dark. That does not happen. The tasks that do not separate models are the ones no model has solved yet, such as dit_pipeline_cfg_alignment_fid_256_001 and atlas_outpost_graybox_navigation. The table shows the mean score by model family on each task, from 0 to 1, and the Spread column gives the gap between the best and worst family. Columns are ordered from strongest to weakest family by mean score across the flagged tasks, shown next to each name. Hover or focus a cell to see how many runs it covers.
A dashed cell means that family has no run on the task.
Method
We scanned every tool call in every archived trajectory for the 22 tasks. We looked for web access, the answer sources the review names, the ALE repository and dataset, grader files and hidden-reference paths, and then read each match in context. Scores come from the recorded evaluation of each run.